7 things you need to know about AI brand visibility tracking
Model settings, question phrasing, web search and sample size affect AI visibility results. Seven things to check before comparing the numbers.

A growing number of companies are starting to track their brand visibility on AI chat platforms. They're running prompts through AI models, counting how often their brand gets mentioned, and building reports off the results.
AI brand visibility tracking isn't like social listening or SEO monitoring. The outputs are sensitive to hidden variables that many marketers have never had to think about. Here are seven things worth knowing before you trust the numbers.
1. Not all mentions are equal
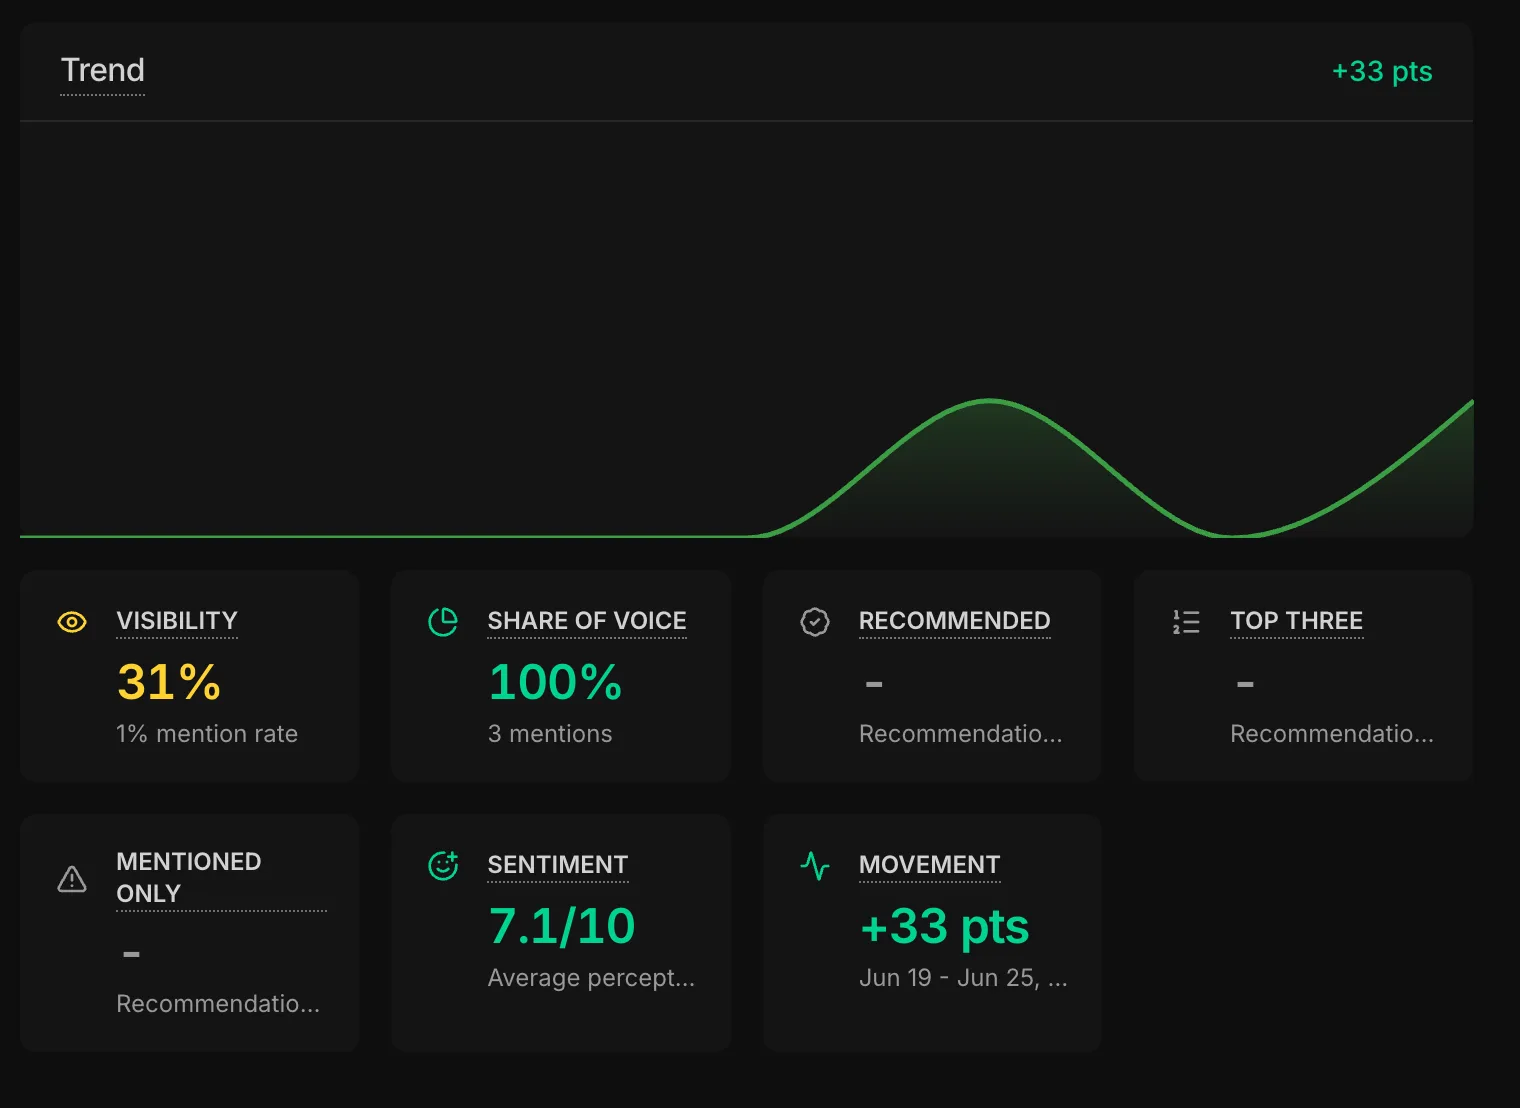
The most common approach is simple: run a batch of prompts, count how many times your brand appears, and report a percentage. Five mentions out of 100 prompts? That's 5% visibility. Job done.
Except it's not. Where your brand appears in a response matters just as much as whether it appears at all. Being mentioned first, as the recommended option, is very different from being listed last as an afterthought. And being described as "the industry leader" tells a different story from being called "a budget alternative."
There are really three things to measure. How often your brand is mentioned (frequency). Where it sits in the response (position). And how it's described (framing). Frequency alone is the shallowest of the three. Position and framing are far more predictive of whether an AI recommendation actually influences a buying decision.
2. The model's settings change which brands show up
Every AI model has a setting called temperature. It controls how predictable or creative the output is. A low temperature means the model plays it safe and gives the most likely answer. A higher temperature means it explores more, surfacing less obvious options.
This has a direct impact on brand visibility. At low temperature, dominant incumbents tend to appear over and over again. Raise the temperature and you'll see more niche and challenger brands enter the mix.
If you don't know what temperature was used in your tracking, you don't really know what you're measuring. Worse, it's easy to accidentally pick settings that flatter your brand or undercount your competitors. For reliable results, you need to fix the temperature and keep it consistent across every test run.
3. Web search changes everything
Some AI models answer purely from what they learned during training. Others search the web in real time before responding. These are fundamentally different scenarios, and they measure fundamentally different things.
When web search is off, you're measuring what the AI "knows" about your brand from its training data. Think of it as embedded mindshare. When web search is on, you're measuring something closer to SEO rankings filtered through an AI layer. The brands that show up are the ones with strong web presence, high domain authority, and content that ranks well in traditional search.
Both are useful metrics. But they answer different questions. And if you're comparing results across models without controlling for whether web search was active, your comparison doesn't hold up. One model might seem to favour your competitor simply because it searched the web while the other didn't.
4. Your prompts shape the answers more than you think
When marketers write test prompts, they tend to phrase them the way they talk about their own category. Something like "What's the leading enterprise SaaS solution for customer relationship management?"
That's not how real people ask. A small business owner is far more likely to type "what's a good CRM for my team of 10?" or "is HubSpot worth it?" Those different phrasings can produce completely different brand recommendations.
If your prompt set doesn't reflect real consumer language, with all its variation in sophistication, budget sensitivity, urgency, and specificity, you're measuring your own assumptions about how people search. Not how they actually search. Good tracking requires prompts that span the full range of how real buyers talk about your category.
5. Small samples will mislead you
Marketers are used to Google rankings being relatively stable. You search something today and tomorrow, you get more or less the same results. AI models don't work that way. Run the same prompt twice and you might get different brands mentioned each time. I.e., AI models are non-deterministic.
This means a small test of 10 or 20 prompts can be wildly unreliable. You might see your brand mentioned in 30% of responses one day and 10% the next. Without running enough prompts (hundreds, not dozens) and checking how stable your results are across repeated runs, you can't tell whether you're looking at a real signal or just noise.
Before drawing any conclusions, run the same set of prompts multiple times and measure how much the results vary. If brand mentions swing by more than 10 to 15% between identical runs, your setup may not be stable enough to trust.
6. Comparing models is harder than it looks
It's tempting to test your brand across ChatGPT, Gemini, Claude, and Perplexity, then declare which one is "best" for your brand. But a fair comparison requires holding everything else constant. Same prompts. Same temperature. Same system instructions. Same web search settings.
There are also subtler traps. Different models produce different response lengths. A model that writes longer answers will naturally mention more brands, which inflates its visibility scores. If you don't normalise for response length (measuring brand mentions as a proportion of total brands mentioned, rather than raw counts) you'll draw the wrong conclusions.
Model comparisons can be genuinely valuable. They can reveal which platforms are more likely to surface your brand organically. But only if the comparison is controlled. Otherwise you're just measuring the differences in your test setup.
7. Using the same model to write and answer your prompts creates a blind spot
This one is subtle, but important. If you use GPT to generate a set of realistic consumer prompts and then test GPT's responses to those prompts, you've created a feedback loop. The model's own biases shaped the questions it's now answering.
It's a form of contamination that doesn't exist in traditional marketing measurement. The fix is straightforward. Generate your prompts with one model (or better yet, base them on real search data and customer research). Then freeze that prompt set. Then test it across whatever models you want to evaluate. Keeping prompt generation and testing separate is one of the simplest things you can do to make your results more trustworthy.
Document your model settings, question list and sampling schedule before comparing results. Review these whenever your setup changes.